
Image to Text OCR (pdf2go)
Install latest/stable of Image to Text OCR
Ubuntu 16.04 or later?
Make sure snap support is enabled in your Desktop store.
Details for Image to Text OCR
Package name
- pdf2go
License
- MIT
Last updated
- 14 October 2026 - latest/stable
- 16 October 2026 - latest/edge
Websites
Contact
Donations
Source code
Report a bug
External link warning
You are about to open
Do you wish to proceed?
Report a Snap Store violation
Report Image to Text OCR for a Snap Store violation
Snap Store Violation Report submitted successfully
Thank you for your report. Information you provided will help us investigate further.
Error submitting report
There was an error while sending your report. Please try again later.
Share this snap
Generate an embeddable card to be shared on external websites.
Extract text from images and scanned PDF documents using Tesseract OCR.
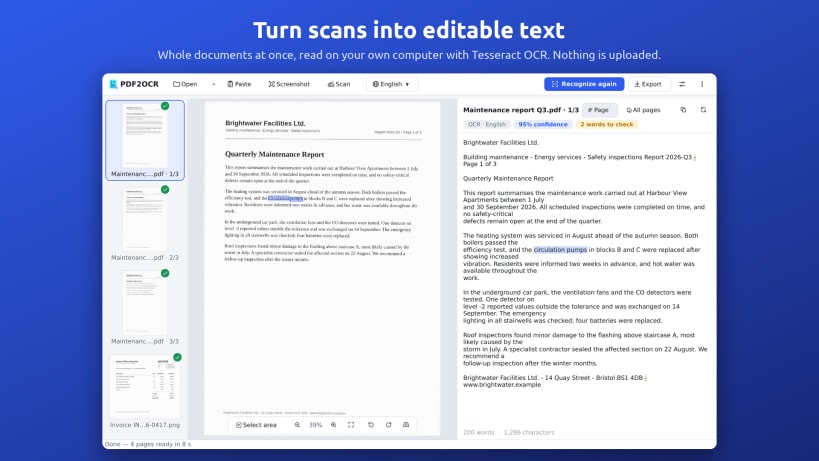
PDF2OCR turns scanned PDFs, photographed pages, images and screenshots into text you can edit, search, copy and save. Recognition runs entirely on your computer with Tesseract OCR: your documents are never uploaded, and the text is never translated or rewritten - you get exactly what is on the page.
Read whole documents at once
- Open PDFs, multi-page TIFFs and images, whole folders, or drag them in
- All pages are recognized in parallel, with progress and a Stop button
- Digital PDFs keep their exact text; OCR is only used where it is needed
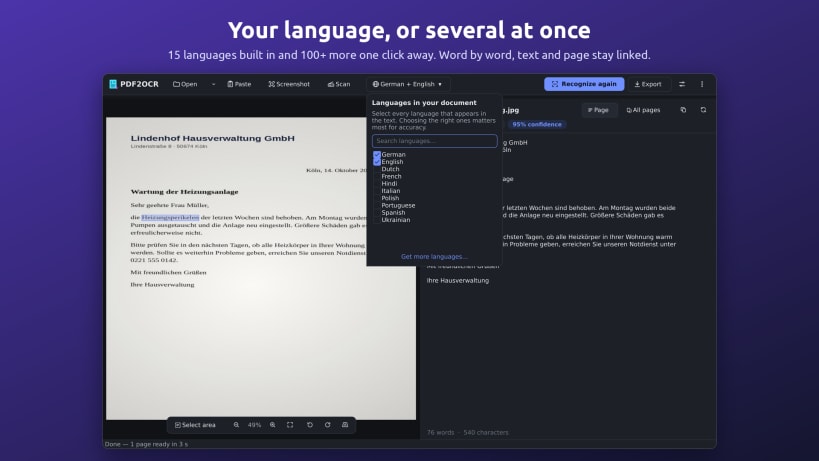
- Pick the languages of your document: 15 built in, 100+ more in one click
Clean results from imperfect sources
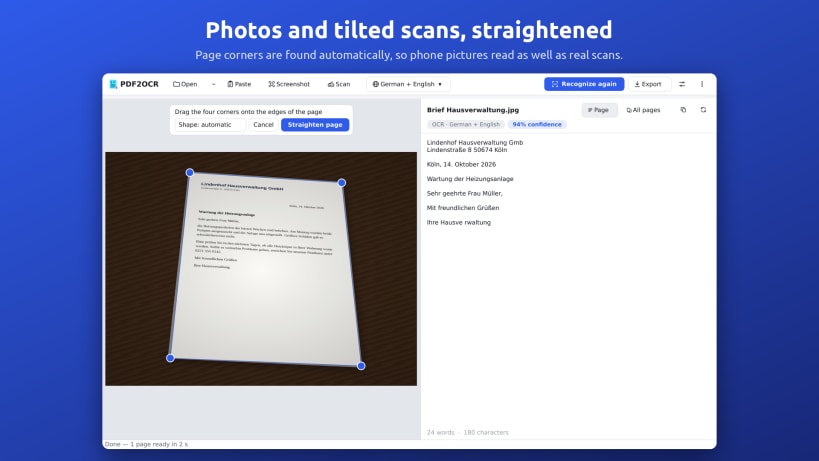
- Sideways, upside-down and slightly tilted pages are straightened automatically
- Photographed pages are flattened: the page corners are found for you
- Optional cleanup for faded scans, coloured paper, specks and small screenshots
- Words that may be misread are flagged in the text and on the page
Get just what you need
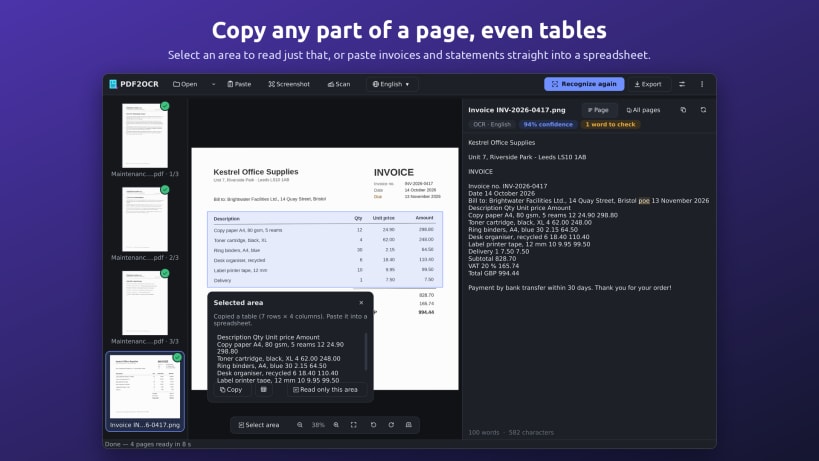
- Select an area of a page to read only that part
- Copy a table and paste it straight into LibreOffice Calc or Excel as cells
- Page image and text are linked word by word for quick proofreading
- Find & replace across all pages
From anywhere
- Paste a screenshot, or capture an area of the screen
- Quick capture: press a keyboard shortcut anywhere and the text of the selected area lands on your clipboard (pdf2go --capture)
- Scan directly from USB and network scanners, including document feeders
Save it your way
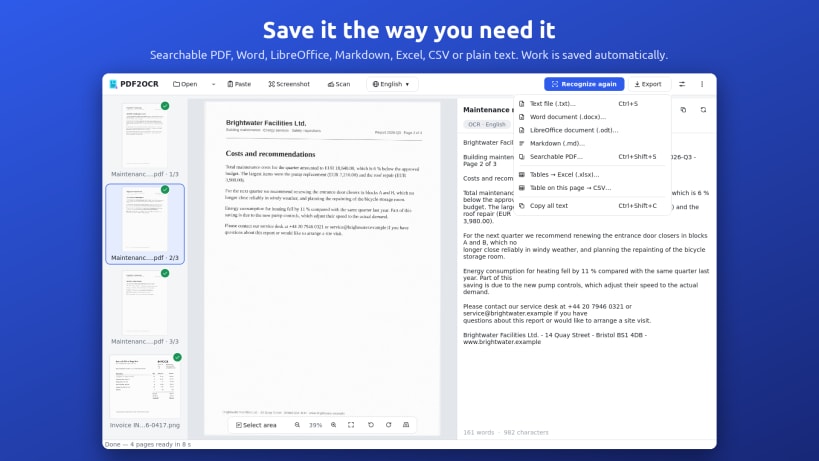
- Searchable PDF, Word, LibreOffice, Markdown, plain text, Excel and CSV
- Your work is saved automatically and comes back after a restart or crash
- Batch conversion from the terminal: pdf2go --to pdf ~/Scans
USB scanners need a one-time permission:
sudo snap connect pdf2go:raw-usb
KEYWORDS:
smallpdf, ilovepdf, freepdfconverter, toolpdf24, adobepdf, jpg2pdf, jpgtopdf, imagetopdf, image2pdf, sejda, pdfonline, sodapdf, pdf2go, itextpdf, image converter, convert jpg to pdf, pspdfkit, pdftools, avepdf, foxit, wondershare, pdfresizer, img2go, img2pdf, online2pdf, bigpdf, pdfelement, nitro, jpg2pdf linux, pdf2go
| Revision | Channel | Version | Build | Commit | Download SBOM |
|---|
The build and commit information is derived from build infrastructure records.
Install Image to Text OCR on your Linux distribution
Choose your Linux distribution to get detailed installation instructions. If yours is not shown, get more details on the installing snapd documentation.


